Document workflows
A practical document intake workflow for a small team
Define one inbox, one minimum record, one review point, and one exception path before adding automation.
· Napdav team
Most document problems begin before extraction. They begin when nobody has agreed where a file should arrive, what minimum information belongs beside it, or who reviews an exception.
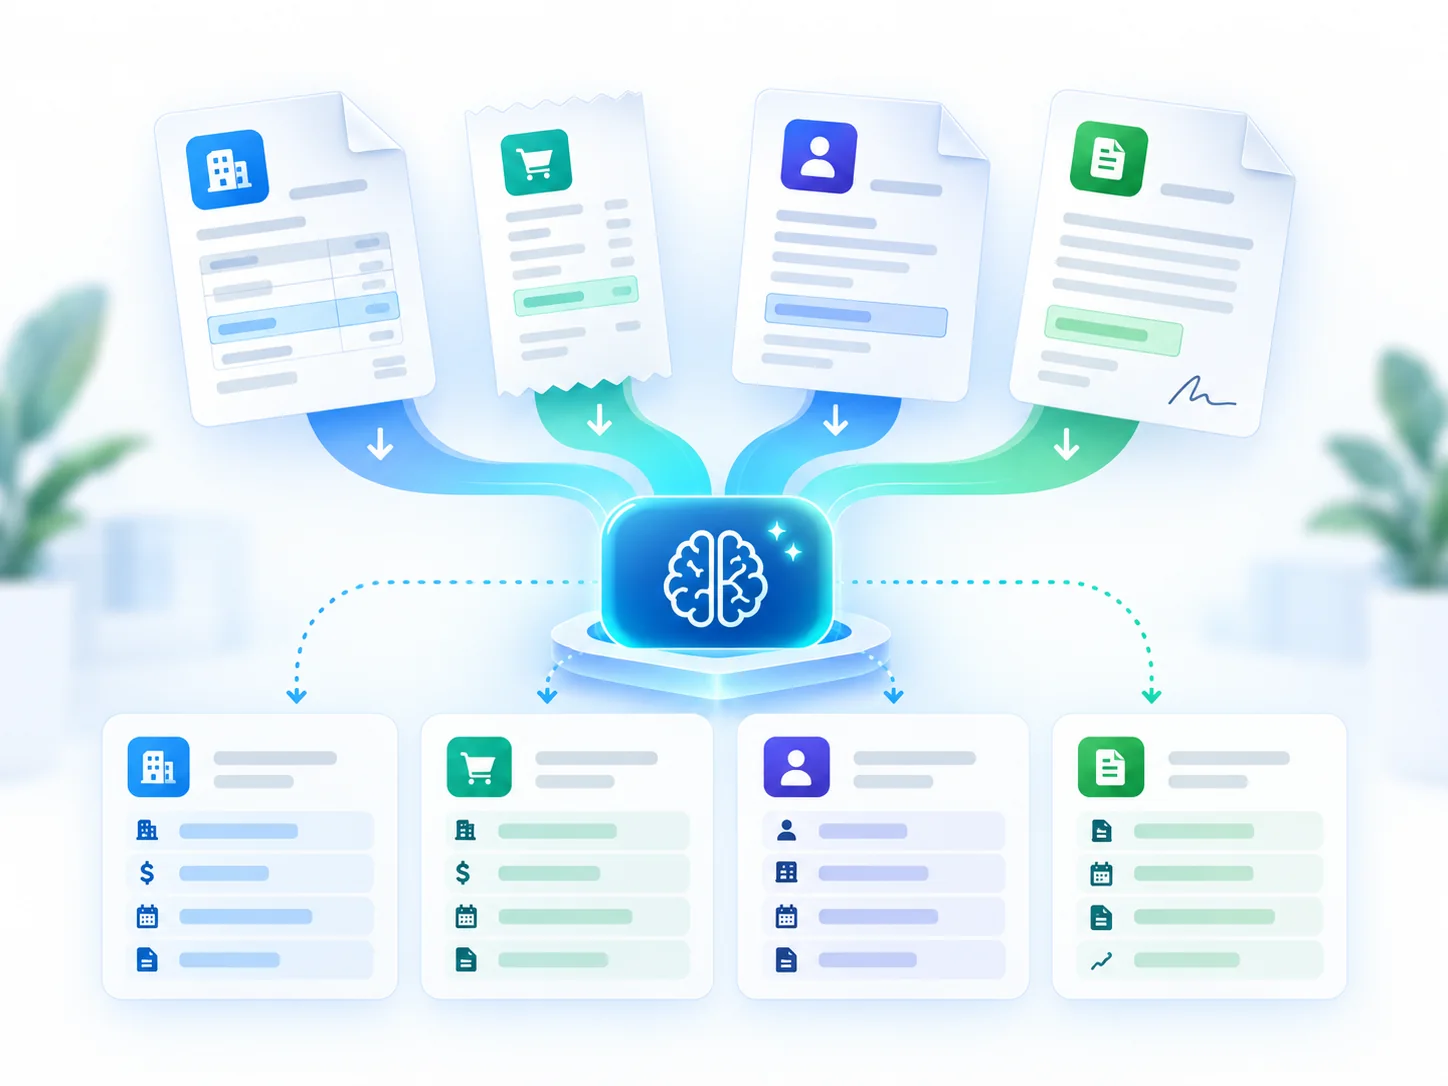
A useful document-intake workflow is small enough to explain without a diagram. The file enters through one channel. A record is prepared. A person confirms what matters. The next action gets an owner. Anything uncertain enters a visible review queue.
Start with one intake point
Choose one place for the workflow you are improving. That might be a forwarding address for supplier invoices, an upload form for receipts, or a shared inbox for employee documents.
The goal is not to move every file in the company on day one. It is to stop one document type from arriving through email, chat, a phone gallery, and somebody's desktop at the same time.
Write down three rules:
- which document type belongs in this intake;
- who may submit it;
- what should happen when the file is unreadable or in the wrong category.
Those rules turn “upload a document” into an operating process.
Define the minimum useful record
Extraction is not valuable because it produces many fields. It is valuable when it prepares the few fields the next person needs.
For an invoice, that may be vendor, invoice number, amount, invoice date, due date, and currency. For an employee document, it may be employee, document type, effective date, expiry date, and access classification.
Keep the original file attached. The structured record makes search and follow-up easier; it does not replace the source. If a value affects payment, employment, compliance, or another consequential decision, the reviewer should be able to compare it with the document immediately.
Put review before automation
A new document type should begin with review. Look for the ordinary failure cases:
- the scan is incomplete;
- the date format is ambiguous;
- two amounts appear on the page;
- the party name differs from the name your business uses;
- the document is valid but belongs to another workflow.
Record corrections rather than treating them as interruptions. They tell you which fields are reliable, which rules need clarification, and where a permanent human checkpoint belongs.
Create one next action
A document should not produce a list of tasks merely because it can. Name the single action that moves the process forward.
An invoice may need review. A contract may need an owner and renewal reminder. An employee file may need approval and an expiry date. Put that action with a person or role, a deadline, and the source record.
This is the point where document management becomes operations: the file has created visible, owned work.
Make exceptions a first-class queue
Automation is easiest to trust when failure is visible. Create one queue for records that are unreadable, incomplete, duplicated, unmatched, or outside the expected range.
The queue should answer four questions without a meeting:
- What happened?
- Which source file caused it?
- Who owns the decision?
- What happens after correction?
Do not label every processed item successful simply because the workflow ran. Completion means the expected record and next action exist, or an exception is waiting with an owner.
Review the workflow, not an invented productivity number
Before promising that automation saves a particular number of hours, verify simpler evidence. Are fewer documents arriving through side channels? Are the required fields usually present? Are exceptions visible? Can another team member find the record and understand its state?
Those observations are enough to decide whether the workflow is becoming more reliable. Quantified savings can come later, from measured work rather than marketing arithmetic.
See how Napdav approaches document management or bring one document workflow to a demo.