Napdav identifies the document, extracts its useful details, and keeps the original searchable—so retrieval does not depend on a perfect filename or folder habit.
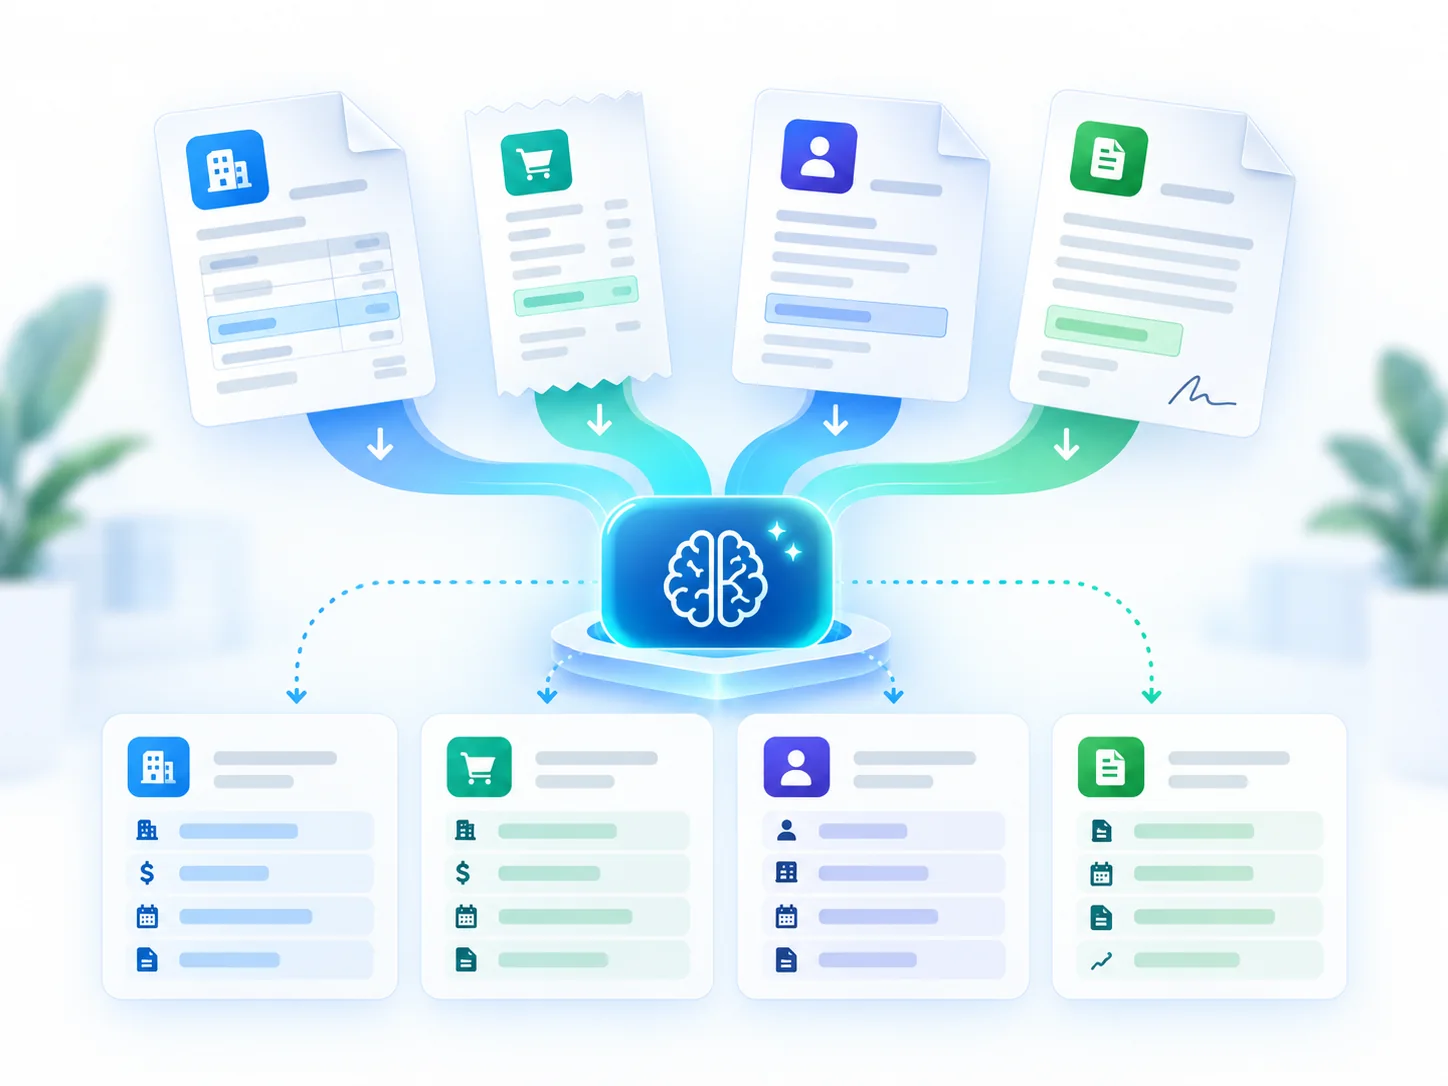
A document can be filed correctly and still be invisible to the person who needs a vendor, date, party, or obligation inside it.
Napdav creates a structured, searchable record while retaining the original document for context and verification.
Identify common business document types during intake.
Expose the dates, parties, amounts, and identifiers inside a file.
Retrieve a record through business details, not only a filename.
Create a reminder or task without separating it from its source.
A small, reviewable loop with a clear source and a clear next action.
Upload or forward the document once.
Identify the document type and relevant fields.
Review the structured record against the original.
Search it, report on it, or create follow-up work.
Outcomes described through mechanisms, not invented time-saving or adoption figures.
The original file remains the evidence. Extracted fields are a prepared view for review, not a reason to discard or ignore the source.
The product direction covers invoices, receipts, contracts, employee files, and common business records. Confirm the exact file formats and limits during setup.
Not necessarily. Napdav is the operational layer around the document. Storage and retention requirements should be confirmed before choosing where originals live long term.
Yes. Human review is part of the intended flow, especially for a new document type.
Use a representative set of documents to test whether categorization and search match the way your business actually retrieves information.